EXECUTIVE OPENING
An evidence-based readiness assessment begins by separating what an organization can demonstrate about its planning decisions from what it merely expects an agent to improve. The report therefore distinguishes documented campaign premises from research hypotheses and evidence still needed to assess enterprise readiness.
RESEARCH STATUS AND METHOD
This is a desk-based evidence map, not a primary survey or measured benchmark. The approved IA-168 (26-10-001) campaign SOF specifies the October 7–17, 2026 single-touch content-syndication window, Supply Chain Now sponsorship, Director/VP audience at enterprises with 1,000+ employees and $500M+ revenue, and healthcare as priority-one industry. The editorial benchmark supplies conceptual framing. Neither source contains a validated cross-company sample of planning-agent deployments or observed financial outcomes. Findings below are structured questions and testable propositions, not statistical results.
EVIDENCE TIER ONE: CONCEPTUAL FRAMEWORK
The benchmark argues for a move from explainable to agentic decision support. This is an editorial proposition useful for framing research questions. It does not by itself establish that agents outperform APS in a specific deployment.
EVIDENCE TIER TWO: TESTABLE OPERATING HYPOTHESES
Potential hypotheses include reduced evidence-gathering time, fewer missing-data handoffs, more consistent scenario comparison, and clearer approval records. Each requires an operational definition, baseline, test period, and credible comparison. None should be represented as observed improvement before measurement.
EVIDENCE TIER THREE: UNSUPPORTED CLAIMS
Do not publish percentage improvements in forecast accuracy, working capital, lead time, service levels, productivity, revenue, or ROI without independently attributable evidence. Do not infer vendor capabilities from a landing-page title. Treat current offer fulfillment as unverified until checked.
HOW TO READ THE EVIDENCE GAPS
A missing baseline means value is unquantified, not necessarily absent. A missing approval matrix means autonomy is not governed, not that the underlying model is incapable. The report should preserve these distinctions and recommend evidence collection rather than inflate confidence.
RECOMMENDED NEXT RESEARCH CYCLE
- Develop a documented sample protocol, interview guide, coding framework, and independent source register.
- Define sample composition and exclusion rules before reporting prevalence or performance.
- Publish methods and limitations alongside any future quantitative findings.
RESEARCH QUESTIONS AND EVIDENCE COLLECTION DESIGN
A readiness map becomes useful when each category is connected to a question that can be answered with records rather than opinions alone. For decision clarity, request an exception policy, a sample escalation, and evidence of who made the final call. For data integrity, inspect representative records and their update histories. For scenario credibility, ask planners to reproduce the assumptions behind an alternative and explain why it was feasible. For governance, test the approval route with a case that exceeds normal limits. For measurement, compare the documented baseline with a defined evaluation period. An interviewee's confidence can guide investigation, but should not substitute for a transaction trace, approval record, or reproducible analysis.
A future empirical study should identify the unit of analysis before recruiting participants. A company, planning team, decision type, and individual exception are not interchangeable units. Sampling only enthusiastic technology sponsors could exaggerate readiness, while sampling only troubled deployments could exaggerate risk. Stratify cases by industry, enterprise complexity, exception frequency, and degree of automation, then disclose recruitment and exclusions. Record whether participants describe a live workflow, a controlled pilot, a prototype, or a proposed future state. A small purposive sample can reveal failure modes and useful design patterns, but cannot establish market prevalence. Any cross-company comparisons must also account for different planning horizons, service definitions and regulatory obligations.
The operational decision owner should explain which exceptions demand action, what information is missing at the point of decision, and which trade-offs are unacceptable. Planning leaders should identify the optimization engine, scenario constraints and circumstances under which they distrust a recommendation. Procurement should describe supplier confirmations and the limits of contractual flexibility. IT and security should document authentication, least-privilege access, audit logs, incident response, and integration ownership. Finance should identify verifiable cost categories and the evidence required to recognize savings. Quality or compliance should identify product, market, or transaction restrictions. Finally, ask each participant to reconstruct the same recent case independently; disagreement between accounts is itself a research finding that needs reconciliation.
Before evaluating technology, define the decision as an observable event. A supplier-delay alert is not yet a decision; the decision might be whether to expedite, transfer stock, change the production sequence, or accept a service exception. Specify the decision deadline, the affected planning horizon, the authority to choose, and the alternatives that can legally and operationally be considered. Then identify which steps are investigation, which are simulation, and which are execution. Without this separation, teams may measure alert-processing speed while ignoring the time required to secure approval or implement an action. The strongest initial use cases have recurring triggers, bounded options, accessible evidence, and an identifiable accountable owner.
Data access is necessary but insufficient. Two systems can use the same term, such as available inventory, to mean different things. One may include quality-held units; another may exclude allocated stock; a third may update only overnight. An agent that combines those values without resolving their meaning could produce a polished but invalid recommendation. Build a source register covering field definitions, ownership, refresh cadence, acceptable latency, and conflict-resolution rules. Test a representative set of records against the source of truth. When a critical field is stale or contradictory, the workflow should disclose the limitation and either request clarification or stop. A confidence label is not a replacement for checking the underlying business semantics.
A scenario should be judged on executability, not merely numerical attractiveness. Reallocating inventory might improve projected service but require transport capacity, transfer authorization, compatible specifications or a customer commitment that does not exist. Request a no-action baseline and alternatives generated under the same planning horizon and constraint set. Record the assumptions, model version, and input snapshot so the comparison can be reproduced. Ask reviewers to identify constraints omitted by the planning model and dependencies that must be resolved before approval. Where alternatives depend on uncertain supplier responses, distinguish conditional outcomes from confirmed plans. The agent's contribution is to make this comparison intelligible and reviewable, not to certify an impossible plan as feasible.
Read permissions, scenario-request permissions, recommendation permissions, and execution permissions should be assessed separately. A system that can summarize inventory data should not automatically be allowed to release purchase orders or modify allocation rules. Define access by role, workflow, site, product class and exposure threshold. Document how approvals are captured and how rejected or overridden recommendations are handled. Examine whether the logs preserve source references, timestamps, user actions, and changes to the underlying assumptions. Include adverse tests: a missing approver, contradictory supplier information, an unusually large transaction, and a prohibited product substitution. The evaluation should establish that the workflow fails safely, not simply that it works under ideal conditions.
Use a measurement ladder that keeps activity, decision quality, and business outcomes distinct. Activity measures include cases processed and packets prepared. Process measures include evidence completeness, review time, escalation frequency, and policy adherence. Decision-quality measures include feasibility, reviewer acceptance, subsequent reversal, and reasons for override. Outcome measures may include service, premium freight, inventory exposure, or production disruption, provided the organization can isolate the effects credibly. Establish a baseline using comparable exceptions, not an anecdote from an unusually difficult week. Where a randomized comparison is impractical, document case matching, seasonality, policy changes, and other confounders. Report uncertainty and missing data rather than presenting modeled effects as realized financial value.
- Stage one is a document and control review: map the decision, sources, owners, and approval policy.
- Stage two is a retrospective replay of selected historical exceptions using only information available at the original decision time.
- Stage three is a supervised shadow workflow in which the agent prepares packets while authorized staff retain the existing process.
- Stage four, if justified, is a bounded live pilot with explicit permissions, stop conditions, and monitoring.
At each stage, specify entry criteria, evidence to collect, an independent reviewer, and exit criteria. A workflow that cannot reproduce its own evidence should not advance because its demonstrations appear persuasive. Likewise, passing one exception class does not justify applying the same controls to unrelated decisions.
For qualitative interviews, develop a coding guide before concluding. Useful codes include missing source, stale record, disputed definition, omitted constraint, unclear owner, delayed approval, infeasible recommendation, accepted recommendation, override, and execution reversal. Allow multiple codes for one case and retain the original evidence excerpt or document reference. Have a second reviewer assess a subset of cases and record disagreements rather than forcing artificial consistency. Distinguish a respondent's perception from an independently inspected artifact. In a future report, present patterns alongside the number and type of cases examined, the method used to select them, and examples that contradict the dominant interpretation. This makes the research more useful without pretending to be statistically representative.
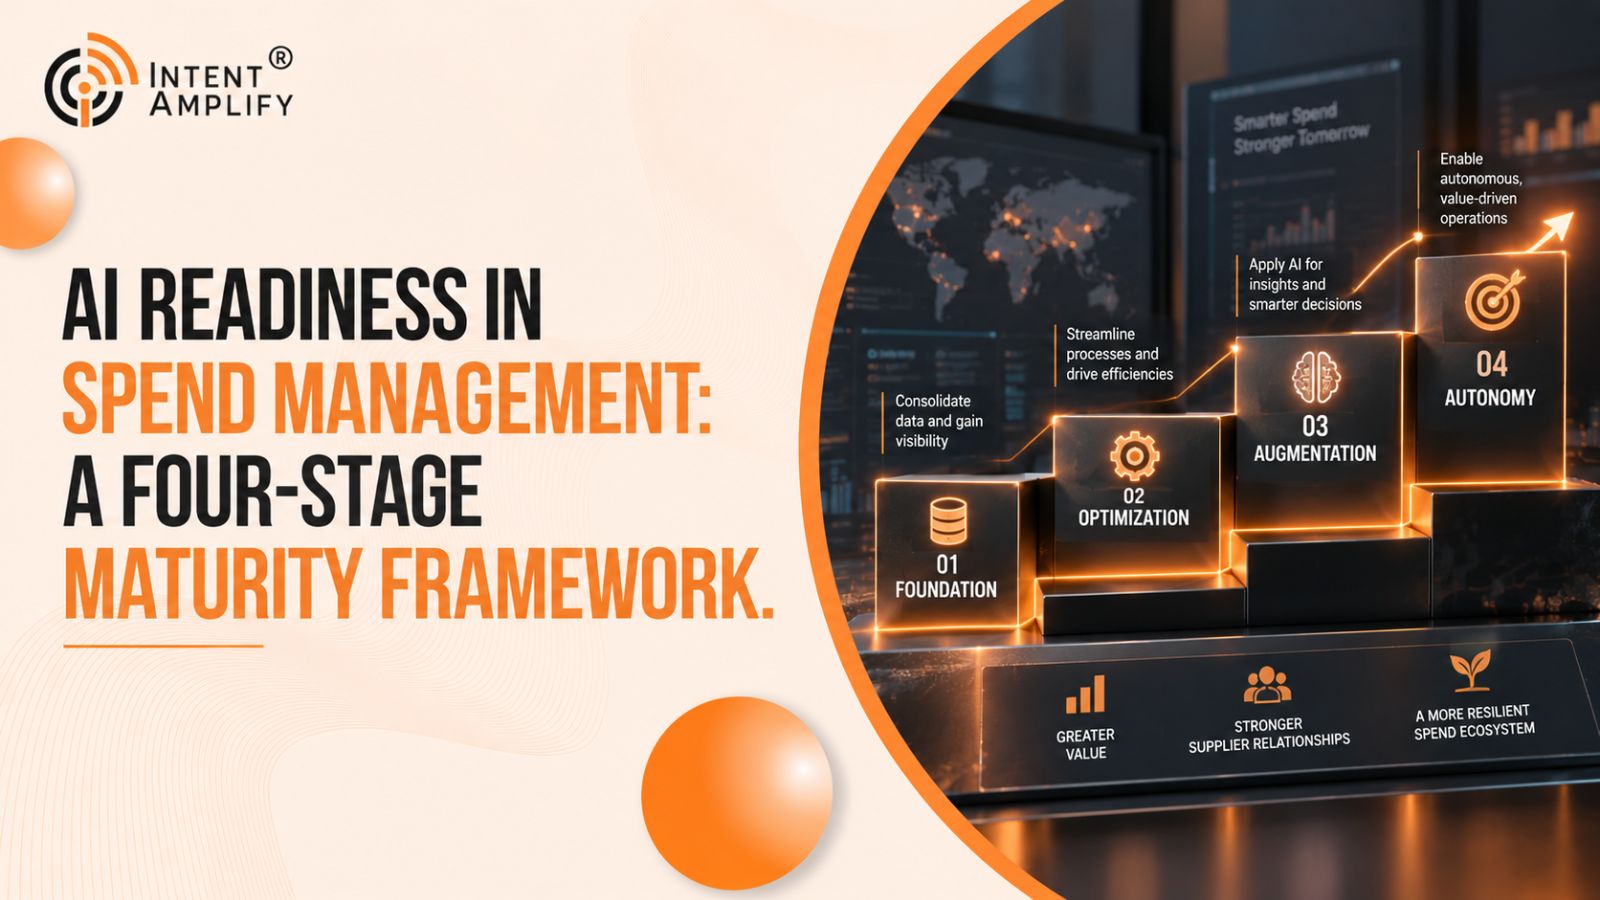
A practical classification can distinguish four conditions without turning them into unsupported market statistics. An evidence-constrained organization lacks dependable records or shared definitions and should first improve source quality. A decision-constrained organization has usable data but unclear ownership, escalation, or policy; its priority is governance. A scenario-constrained organization can investigate exceptions but cannot reproduce feasible alternatives, suggesting work on planning models and constraints. A controlled-pilot candidate has defined decisions, credible evidence, authorized reviewers, and measurable baselines. These are diagnostic categories, not maturity scores validated across enterprises. A single enterprise may occupy different categories for different products, regions, or exception types, so readiness should be assessed at the workflow level.
An economic case should distinguish labor capacity released from cash savings actually realized. Faster preparation of a decision packet may improve responsiveness without reducing payroll expense. Avoided expedites should be tied to actual freight alternatives and confirmed actions, not simply a model's lowest-cost scenario. Inventory improvements require evidence of changed positions and carrying costs, with attention to demand shifts and policy changes. The cost side should include integration, source remediation, testing, security, monitoring, exception support, training, and periodic control reviews. Finance should approve the definitions and attribution method before outcomes are reported. If a credible counterfactual is unavailable, describe the benefit as directional or modeled and explain the limitation.
Readiness testing should actively seek failures. An agent may cite a source correctly but misread its business meaning; request a valid scenario using an outdated inventory snapshot; or summarize an option without its approval dependency. Users may also accept a recommendation because it appears authoritative, especially under time pressure. Set stop conditions for critical missing data, irreproducible analysis, approval-policy breaches, repeated infeasible scenarios, and unexplained execution mismatches. Assign an owner with authority to suspend the workflow. Preserve incident records and require remediation evidence before restarting. Monitoring should cover not only model output but also upstream data changes, integration permissions and evolving business policies.
Future publications should separate documented facts, observed pilot results, respondent perceptions, and hypotheses in both prose and charts. Every quantitative figure should identify its numerator, denominator, period, source, population, and exclusion rules. Disclose whether the result reflects a simulation, shadow mode, or production operation. Explain how outcomes were attributed and whether the sample was large enough to support generalization. Negative results and cases where human reviewers rejected the recommendation are part of the evidence, not editorial noise. Until that standard is met, the defensible conclusion is a readiness framework and research agenda rather than a claim that planning agents deliver a universal performance advantage.
CONCLUSION
Evidence mapping and readiness should be treated as an accountable decision system, not a promise of effortless autonomy. Begin with a bounded workflow, record the evidence, preserve human authority, and measure consequences before expanding.
Explore the Supply Chain Now campaign resource: Beyond APS: Why Your Next Supply Chain Breakthrough Is a Planning Agent.
REFERENCES
The following are external context sources; they do not establish that any specific product, deployment, or campaign achieved the outcomes discussed in this asset.
1. Gartner, AI Orchestration Operating-Model Survey (2026-05-06)
2. Gartner, Data Semantics and Agent Accuracy (2026-05-11)
3. Gartner, AI Skills in Supply Chain (2026-06-15)
4. Gartner, Top Supply Chain Technology Trends (2026-06-30)
5. Gartner, Agent Washing in Supply Chain Planning (2026-05-20)